Introduction Metadata Model
All the research produced in the CropXR consortium will be well annotated with metadata following the CropXR standards.
The metadata annotation will have multiple uses:
- Findability of your study, by other researchers in the consortium
- Reusability of your data by other users in the consortium
- Improvement of your own data annotation
The responsibility to annotate the data lies with the researcher, with the help and tools provided by DataXR.
Model flexibility
A standardized metadata format ensures that the metadata has a predictable structure. There are however many different types of studies in the consortium, with different metadata that is important. To fit all different studies in the same format there is a certain flexibility in the model. This means you need to understand the model well and decide how to apply it to your study. These documents should provide the information needed to make those choices. For the first time entering metadata, plan sufficient time to understand the model. If you are stuck at any point, things are unclear, or you need help, please reach out to the DataXR team at data@cropxr.org
Standards
The CropXR metadata model is made up from a combination of established standards for metadata on plant research:
- Phenotyping ISA + MIAPPE
- Sequencing ISA + ENA for plants + ENA for crops + additional fields based on LettuceKnow experience.
MIAPPE and ENA give a standardized way to describe the setup of a study, the experimental conditions, the types of measurements performed, and how the output data relates to them, down to sample level. This detailed standardized description facilitates the findability and reusability of the data. Because both standards describe the setup of a plant experiment, there is a large overlap between the standards. To make the metadata uniform, and to be able to describe combined experiments, the standards have been combined into a unified metadata model. In this model, you can describe the plants and growth conditions on study level and from there start multiple types of measurements.
The ISA format is widely used to represent research data. It is often used to represent MIAPPE data. The catalogue uses the ISA structure, somewhat adapted. This page will explain how the standards fit into the catalogue data model.
Assay and sample definition
In the ISA format, you can perform assays on samples. It assumes that in an experiment, there are several steps called a process. Each process has an input and an output and a protocol, that describes how the output was created from the input. The input can be either a material or data, and the output as well. These processes can be chained together. Here is an example:
step 1 sample collection (input plant material-> output sample)
step 2 DNA extraction and library prep (input sample -> output sample)
step 3 sequencing (input sample -> output data)
step 4 analysis (input data -> output data)
In ISA these processes are organized the following way: the study contains 1 process with a material input (study source) to a material output (study sample). The other processes, however many needed, are grouped under the assay. The assay can consist of several steps/processes and starts with the study sample.
In the catalogue, the processes that are grouped under the assay, are all called an assay even if the input and output are both a material object, or both data files. This does not fit with the classical meaning of the word ‘assay’, but it implements the same functionality as ISA. The assays can be connected into an assay stream.
In the catalogue, every row is called a ‘sample’, even when it describes an assay performed on a sample or the derivation of a data file.
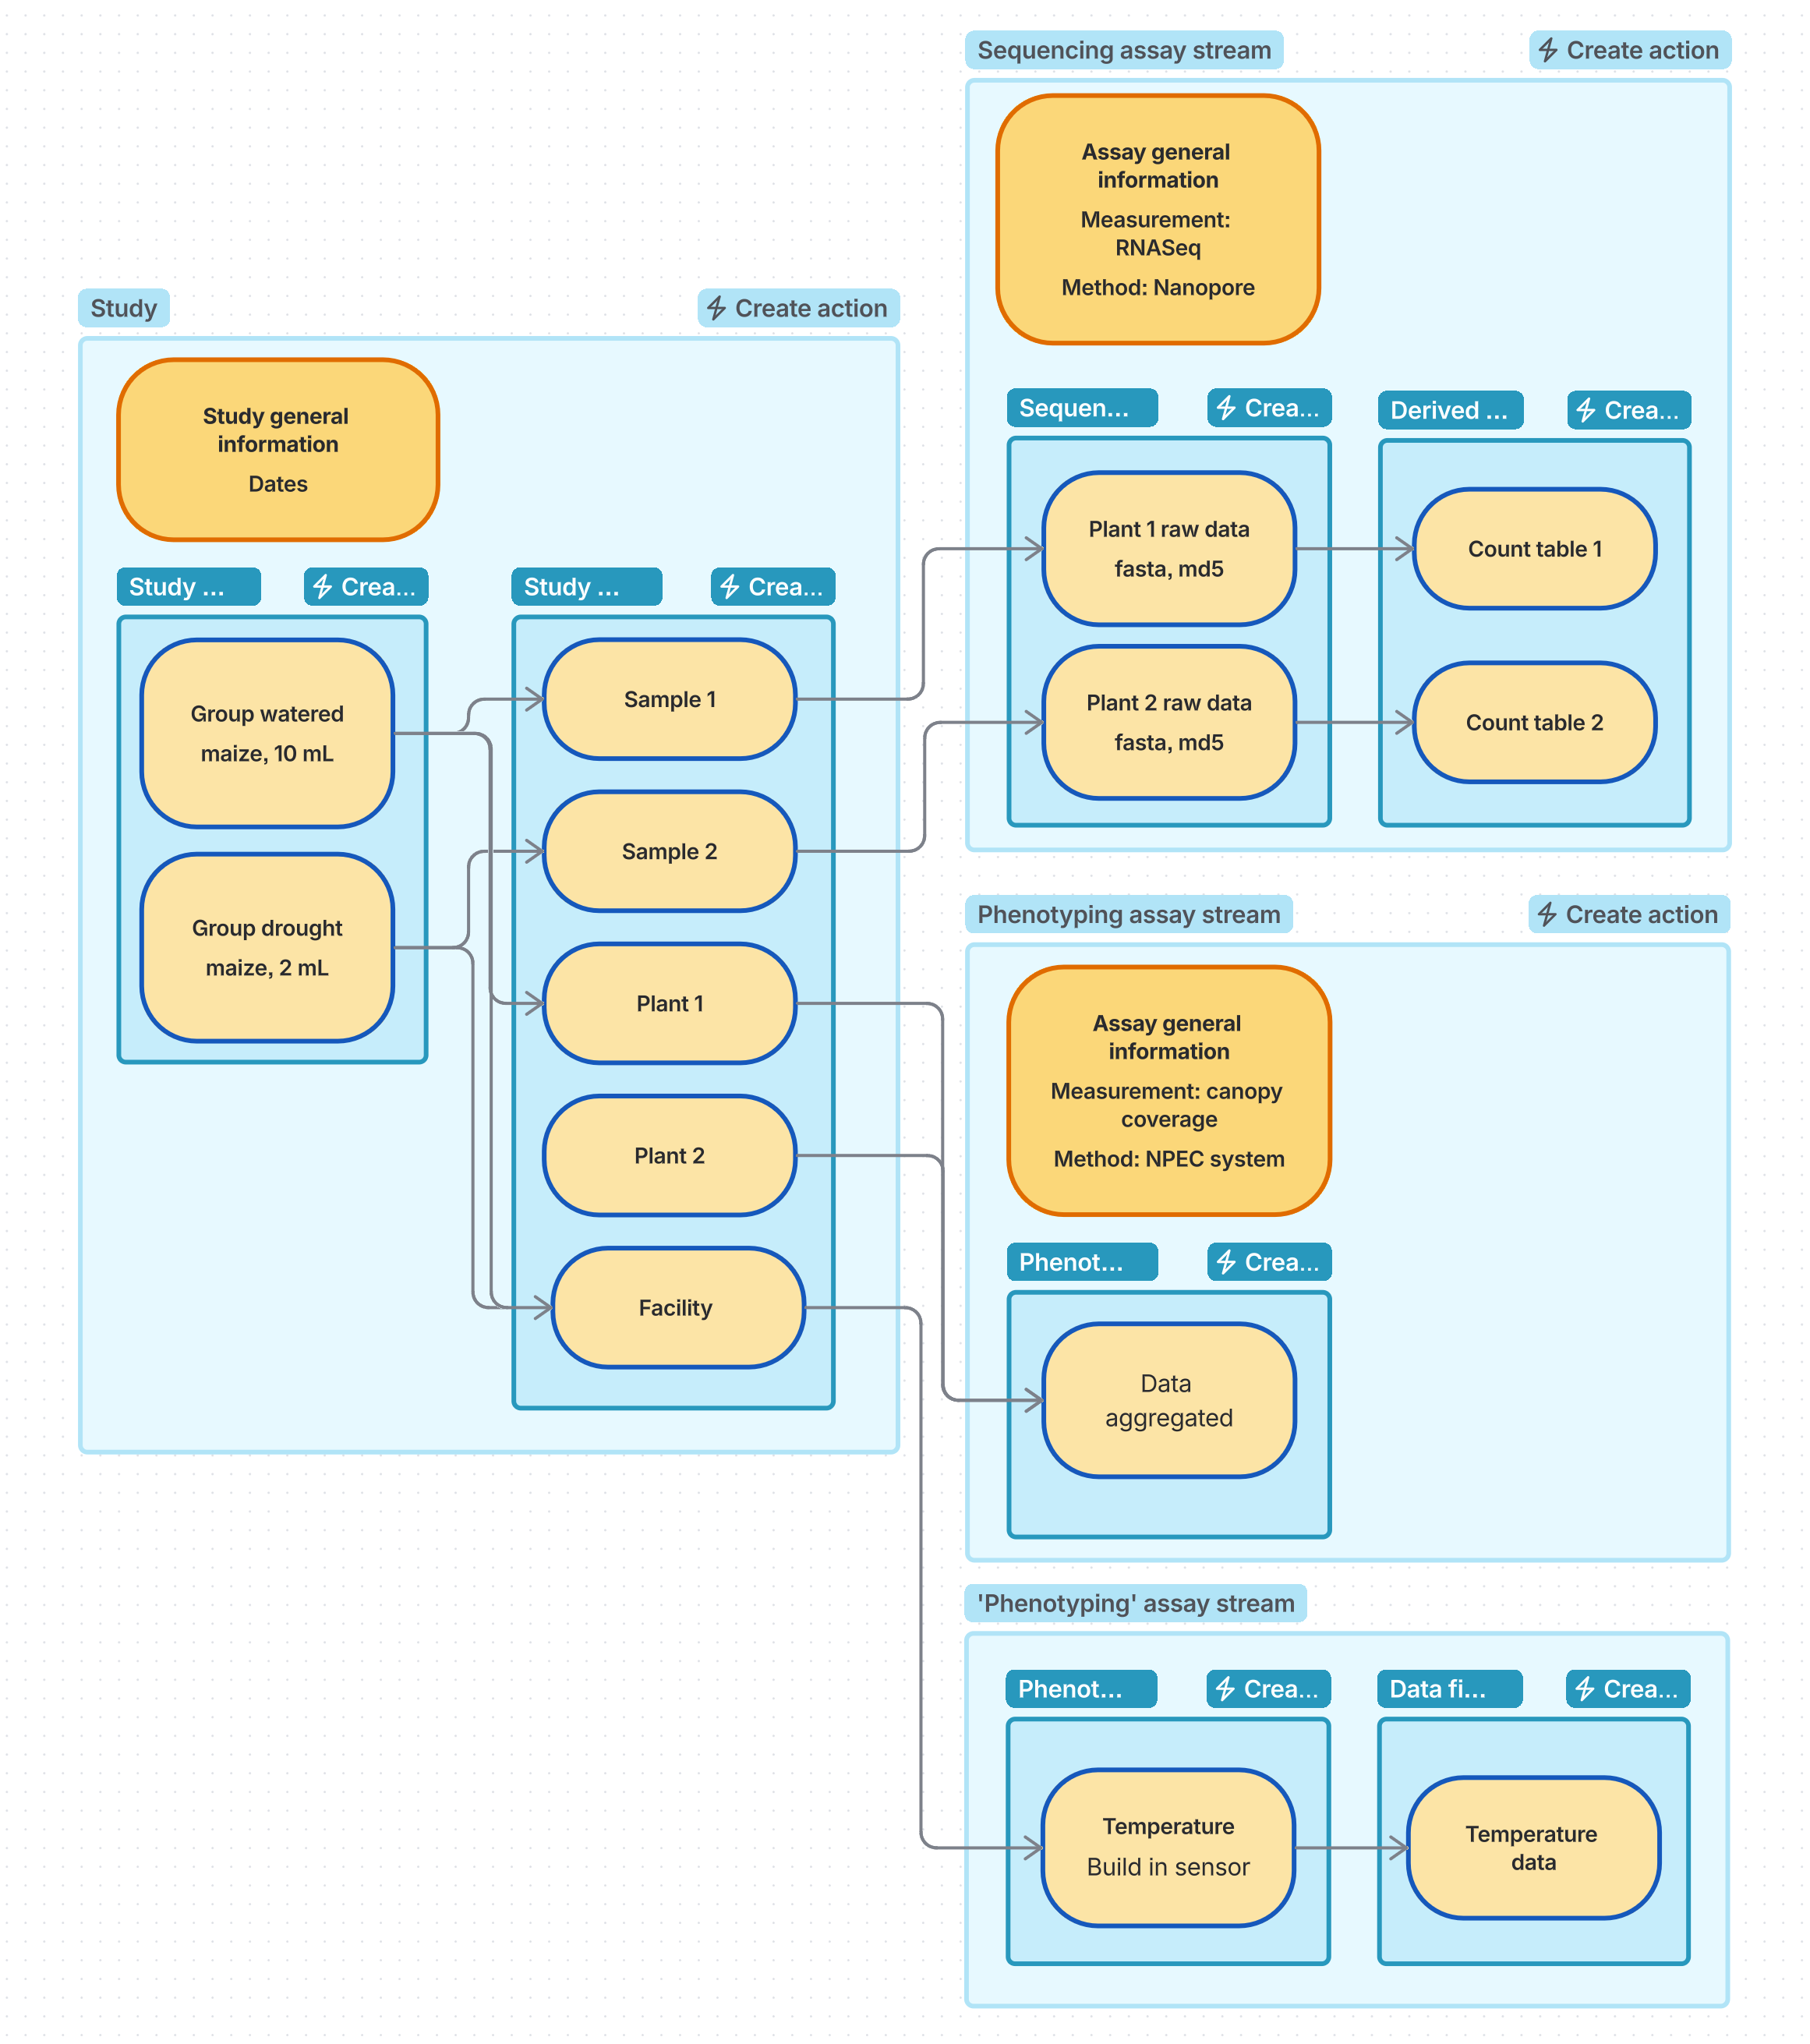
Practical
Relevant columns
Not all fields are relevant to each study.
Fixed or free fields
Some fields are free text, some you need to pick from a list (controlled vocabulary), some are free, but with a list of suggestions to pick from.
Sections
Study extended metadata
Information that is the same for the whole study.
Study sources
The study sources section describes the plant, the growth conditions, the treatment.
Besides the standard parameters that are suggested, it is possible to include additional parameters. Use the MIAPPE lists for growth conditions and experimental factors for predictable descriptors of relevant parameters. Not all conditions are as relevant and need to be included in the metadata.
Choose the granularity that is needed for your metadata. The sources are used to specify the biological material, as well as the growth conditions. At least each experimental block needs to be defined as a separate source. If you need to trace a sample back to an individual plant, define one source per plant.
Study samples
An observation unit is any level on which a measurement/observation is done. Examples are a plant, plot or whole field or greenhouse. A sample is a special level: it describes a physical subset of the plant that is collected for analysis. It will contain some information about sampling.
Both samples and observation units are listed under the study samples section. The units can be nested.
How you define them depends on the design of your study. Usually it is the unit for which an experiment produces a file. Think about the assays and the data files when defining the observation units.
Phenotyping assay extended metadata
Each different type of phenotyping measurement will be represented by an assay stream. The observed variable describes the measurement: what was measured and how, including the instrument. It can be used to describe any type of measurement. This is important, because phenotyping does not rely on a limited set of experiments. It does require you to describe the measurement in the format.
As more people annotate their metadata, it will be valuable to create a CropXR internal reference that shows how others have described the same or similar experiments.
In the assay stream extended metadata the information that is the same for each individual measurement can be captured.
Assay rows
Each row describes a measurement on a sample or observation unit. Include any info that is different per performed measurement and/or not captured in the assay extended metadata. Typically include the data file location of the output of a measurement.
General assay
When multiple measurements are done, each generating only few outputs, it is easier to describe these measurements without needing to create a separate assay stream for each. It is possible to make a general assay that includes multiple measurement types.
In this assay there is no extended metadata on assay stream level. Each row describes the assay: what was measured and how. In a next assay step the data file can be linked to the assay.
Derived data files
For derived data files a separate assay step can be added. The input is an output file from the previous step and the method of data derivation can be included.
Entity-relationship diagrams
Not every diagram applies to every study. Jump to the ones you need:
- Containers and study-level metadata: properties of the whole study and assay stream. All studies.
- The source: the plant, its growth conditions and treatment. All studies.
- Sequencing stream: samples, sequencing assays and data files. Sequencing studies.
- Phenotyping stream: observation units, observations and data files. Phenotyping studies.
- Combined sample: one sample template for studies that record more than one stream, used with the assays of each stream it records. Combined studies.
- What the model cannot express: known limitations. Worth reading before you start.
The diagrams below show model 1.0, the last per-file state of the definitions from 260727 before templates were renamed by stream. Every box is a table in the catalogue, and every row of every table is a "sample" to SEEK. PK marks the column SEEK displays as the row's name; it must be unique within the table. FK marks the Input column, a list of rows from the table one level up. cv is a controlled vocabulary, link is a reference to a record registered elsewhere in the catalogue. Fields marked REQ are required; the rest are optional.
Containers and study-level metadata
Whole-study and whole-assay properties do not sit in the tables. They sit on the Study and the assay stream as extended metadata, one type per stream. The phenotyping and combined study types embed nested records for location, experimental design and growth facility. The sequencing study type carries only the study id and the dates.
erDiagram
    INVESTIGATION ||--o{ STUDY : contains
    STUDY ||--o{ ASSAY_STREAM : contains
    ASSAY_STREAM ||--|{ ASSAY : contains
    STUDY ||--o| STUDY_METADATA : "extended metadata"
    ASSAY_STREAM ||--o| ASSAY_METADATA : "extended metadata"
    STUDY_METADATA ||--o| LOCATION : links
    STUDY_METADATA ||--o| EXPERIMENTAL_DESIGN : links
    STUDY_METADATA ||--o| GROWTH_FACILITY : links
    STUDY ||--|| SOURCE_TABLE : "study source"
    STUDY ||--|{ SAMPLE_TABLE : "study sample"
    ASSAY ||--|| ASSAY_TABLE : "assay - material or assay - data file"

    STUDY_METADATA {
        string study_id PK "REQ"
        string study_start_date
        string study_end_date
        text cultural_practices
    }
    LOCATION {
        string experimental_site_name
        string latitude
        string longitude
        string altitude
        cv country
    }
    EXPERIMENTAL_DESIGN {
        text experimental_design_description
        string experimental_design_type
        string observation_unit_level_hierarchy
        text observation_unit_description
    }
    GROWTH_FACILITY {
        text growth_facility_description
        string growth_facility
    }
The study types are CropXR phenotyping study, CropXR sequencing study and CropXR combined study. The assay types are shown in the stream diagrams below.
The source, shared by both streams
One source row is a genotype or seed batch together with the conditions it was grown under before treatment (growth_*) and during treatment (treatment_*). Those conditions apply to every sample and file derived from the row, so anything that varies per plant belongs on the sample instead. A source can hold one treatment.
erDiagram
    SOURCE {
        string Source_Name PK "REQ"
        cv country
        int taxon_id
        string species_name
        string genotype
        string genebank
        string ecotype
        string cultivar
        string latitude
        string longitude
        string altitude
        string sex
        string seed_batch_id
        string growth_conditions
        string growth_facility_description
        string growth_facility
        cv growth_medium
        string growth_light_regimen
        real growth_temperature_day
        real growth_temperature_night
        real growth_light_intensity
        real growth_light_rfr_ratio
        cv experimental_group
        text treatment
        string treatment_ontology
        string treatment_growth_medium
        string treatment_light_regimen
        real treatment_temperature_day
        real treatment_temperature_night
        real treatment_light_intensity
        real treatment_light_rfr_ratio
        string treatment_time_duration
        string treatment_time_of_day
        string treatment_chemical
        string treatment_chemical_cas_id
    }
Sequencing stream
The library fields follow ENA and sit on the assay stream's extended metadata, because they hold for every sample sequenced in that assay. The assay row therefore carries little more than an id and the library construction protocol. It is followed by CropXR sequencing data file, one row per file.
erDiagram
    SOURCE }|--o{ SAMPLE : Input
    SAMPLE }|--o{ SEQUENCING_ASSAY_CONDENSED : Input
    SEQUENCING_ASSAY_CONDENSED }|--o{ SEQUENCING_DATA_FILE : Input
    SAMPLE }|--o{ SEQUENCING_ASSAY_AND_DATA_FILE : Input
    SEQUENCING_DATA_FILE }o--|| DATA_FILE_RECORD : file_location
    SEQUENCING_ASSAY_AND_DATA_FILE }o--|| DATA_FILE_RECORD : file_location
    SEQUENCING_ASSAY_METADATA ||--o{ SEQUENCING_ASSAY_CONDENSED : "assay stream"

    SAMPLE {
        link Input FK "REQ"
        string subject_id PK "REQ"
        string title "REQ"
        string description
        string protocol "REQ"
        date collection_date
        date biochemical_extraction_date
        date sequencing_submission_date
        string plant_structure_ontology
        string plant_structure
        string age
        string plant_developmental_stage_text
        string plant_developmental_stage_ontology
        string spatial_distribution
        string external_id
        text remarks
    }
    SEQUENCING_ASSAY_CONDENSED {
        link Input FK "REQ"
        string experiment_id PK "REQ"
        string library_construction_protocol "REQ"
        string design_description
        string external_id
    }
    SEQUENCING_DATA_FILE {
        link Input FK "REQ"
        string file_name PK "REQ"
        link file_location "REQ"
        text file_description
        string protocol "REQ"
        cv file_type
        string md5_checksum
        string external_id
        cv raw_or_derived
    }
    SEQUENCING_ASSAY_AND_DATA_FILE {
        link Input FK "REQ"
        string design_description
        string file_name PK "REQ"
        link file_location "REQ"
        text file_description
        string protocol "REQ"
        cv file_type
        string md5_checksum
        string external_id
        cv raw_or_derived
    }
    SEQUENCING_ASSAY_METADATA {
        string study_external_id
        cv study_type
        string library_construction_protocol
        string design_description
        cv library_source
        cv library_strategy
        cv library_selection
        cv library_layout
        string insert_size
        cv platform
        cv instrument_model
    }
    DATA_FILE_RECORD {
        string title
        string remote_url
    }
Phenotyping stream
The study sample is an observation unit: the plant, plot, greenhouse or other level on which a measurement is made. Units can nest through parent_subject_id, which is a name and not a checked link. The observed variable, method, instrument and scale can be described once on the assay stream's extended metadata, or per row in CropXR phenotyping assay when they differ between rows. Files are recorded in CropXR phenotyping data file.
erDiagram
    SOURCE }|--o{ OBSERVATION_UNIT : Input
    OBSERVATION_UNIT }|--o{ OBSERVATION : Input
    OBSERVATION }|--o{ DATA_FILE : Input
    OBSERVATION_UNIT }|--o{ CONDENSED_OBSERVATION_ASSAY_WITH_DATA_FILE : Input
    DATA_FILE }o--|| DATA_FILE_RECORD : file_location
    CONDENSED_OBSERVATION_ASSAY_WITH_DATA_FILE }o--|| DATA_FILE_RECORD : file_location
    PHENOTYPING_ASSAY_METADATA ||--o{ OBSERVATION : "assay stream"

    OBSERVATION_UNIT {
        link Input FK "REQ"
        string subject_id PK "REQ"
        string title "REQ"
        string description
        string type "REQ, the protocol"
        string plant_structure_ontology
        string plant_structure
        string age
        string plant_developmental_stage_text
        string plant_developmental_stage_ontology
        string observation_unit_type
        string parent_subject_id
        string spatial_distribution
        text remarks
    }
    OBSERVATION {
        link Input FK "REQ"
        string experiment_id PK "REQ"
        string variable_name
        string variable_accession_number
        string trait
        string method "REQ, the protocol"
        string method_accession_number
        string method_description
        string reference_method
        string instrument
        string instrument_metadata
        string scale
        string scale_accession_number
        string time_scale
    }
    DATA_FILE {
        link Input FK "REQ"
        string file_name PK "REQ"
        link file_location "REQ"
        text file_description
        string protocol "REQ"
        string file_type
        string md5_checksum
        cv raw_or_derived
    }
    CONDENSED_OBSERVATION_ASSAY_WITH_DATA_FILE {
        link Input FK "REQ"
        string protocol "REQ"
        string file_name PK "REQ"
        link file_location "REQ"
        text file_description
        string file_type
        string md5_checksum
        cv raw_or_derived
    }
    PHENOTYPING_ASSAY_METADATA {
        string variable_name
        string variable_accession_number
        string trait
        string method
        string method_accession_number
        string method_description
        string reference_method
        string instrument
        link instrument_metadata
        string scale
        string scale_accession_number
        string time_scale
    }
    DATA_FILE_RECORD {
        string title
        string remote_url
    }
Combined sample
A study that records more than one stream can use CropXR combined sample instead of a stream's own sample template. It carries the union of the sequencing sample, phenotyping observation unit and metabolomics sample fields plus a subject_type that says which one a row is.
erDiagram
    SOURCE }|--o{ SAMPLE_OR_OBSERVATION_UNIT : Input
    SAMPLE_OR_OBSERVATION_UNIT }|--o{ SEQUENCING_ASSAY_CONDENSED : Input
    SAMPLE_OR_OBSERVATION_UNIT }|--o{ OBSERVATION : Input

    SAMPLE_OR_OBSERVATION_UNIT {
        link Input FK "REQ"
        string subject_id PK "REQ"
        cv subject_type "REQ"
        string title "REQ"
        string description
        string protocol "REQ"
        date collection_date
        string biochemical_extraction_date
        date sequencing_submission_date
        string plant_structure_ontology
        string plant_structure
        string age
        string plant_developmental_stage_text
        string plant_developmental_stage_ontology
        string observation_unit_type
        string parent_subject_id
        string spatial_distribution
        string external_id
        text remarks
    }
What the model cannot express
- A link between rows of different studies.
- A derived file whose inputs come from two assay streams.
- More than one treatment on a source.
- An observation unit hierarchy that the catalogue checks.
- Metabolomics measurements.
Field descriptions and vocabulary terms are listed in the metadata definitions repository.
Outlook
In the future the catalogue will be extended to cover metabolomics data.
The catalogue can be improved with small suggestions based on researcher feedback.
There will be a way to export the metadata into an ENA format for easy submission. There will be an importer that can import published ENA metadata into the format of the catalogue.